Trust in Rightview Agents
When we set out to build Rightview, we knew we were after both high-performance and, more importantly, clinical-grade trust.
Agents are notoriously hard to productionalize properly, especially in a protected domain like clinical trials. In order to maintain quality, our development and production cycles go through a series of rigorous test gates that give us conviction in new features - and in our product. This is what it means to build and iterate on production agents as fast as we do - coding agents give us scale but our trust process gives us confidence.
We ship fast, but nothing ships on blind trust
We merge 85% of our code changes in less than four hours - even as our code volume accelerates.
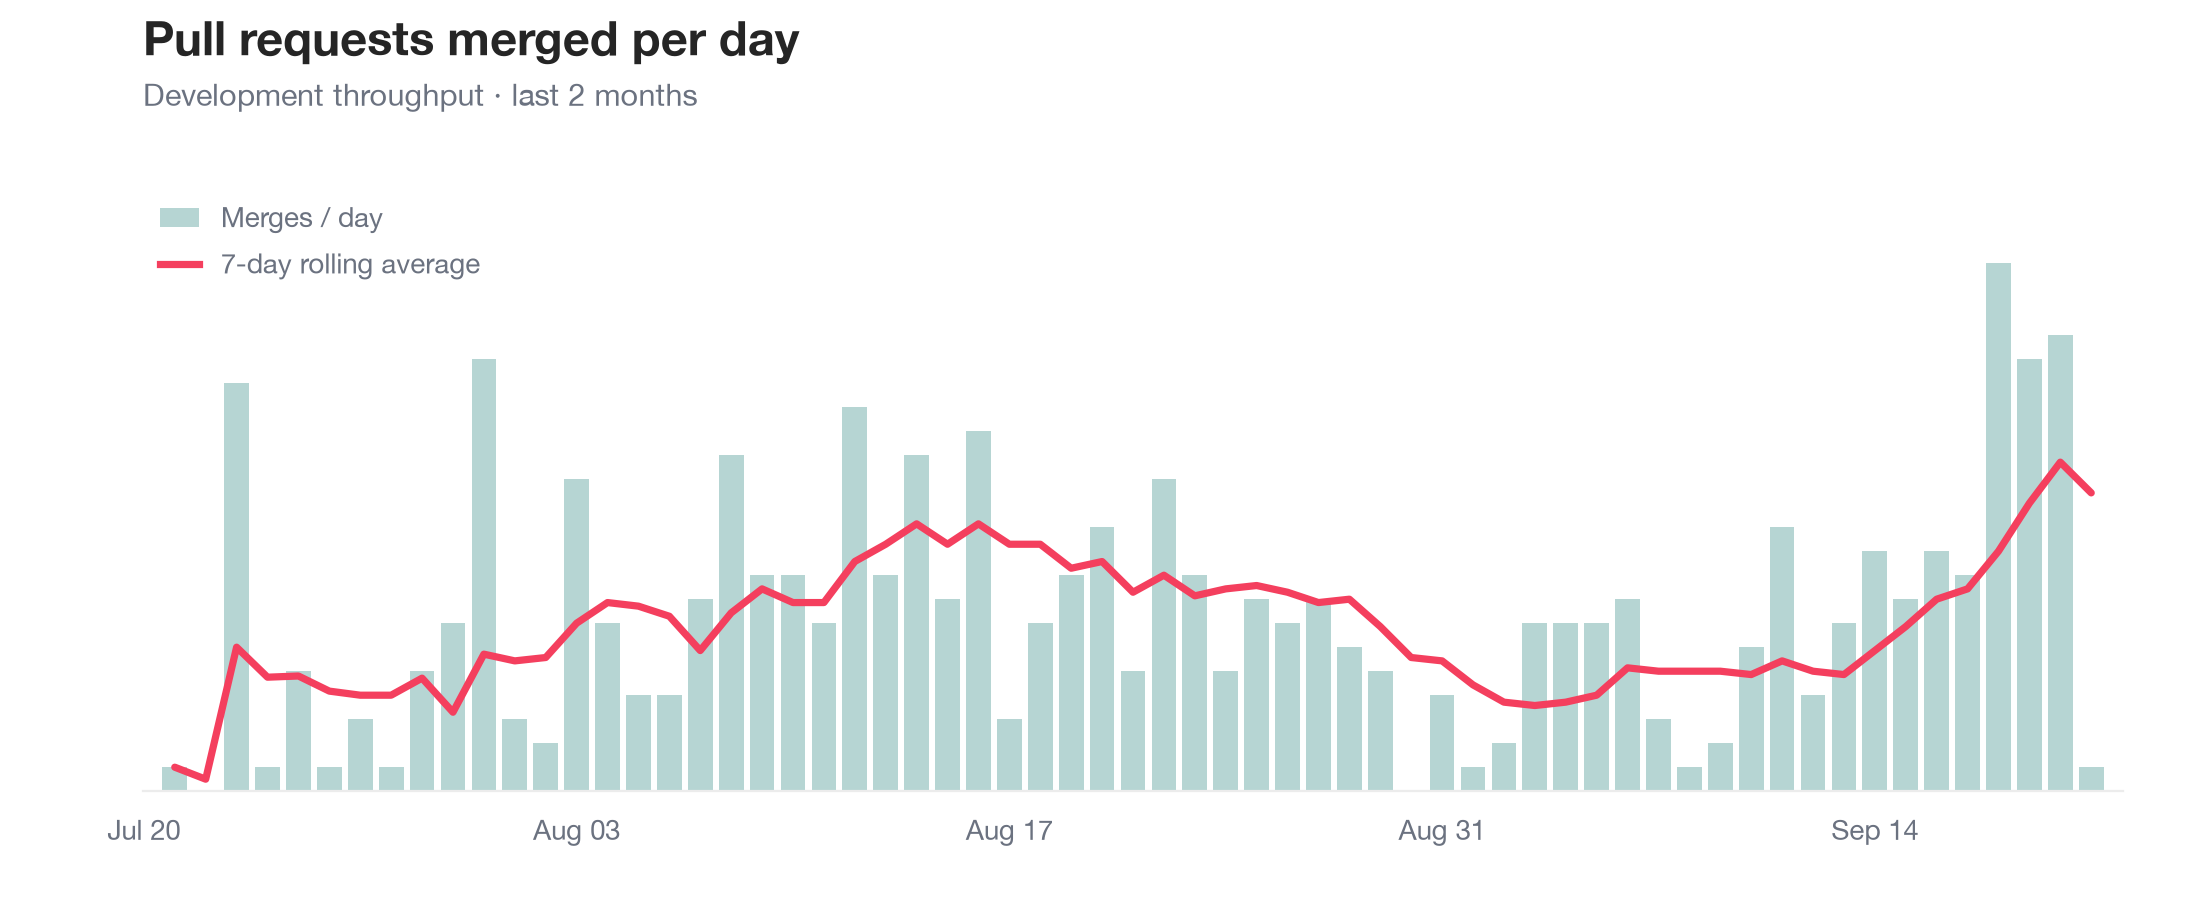
We ship fast, but nothing ships on blind trust. Roughly a quarter of our substantive changes (23.9%) get stopped at test gates and require iteration before they earn their way into the product. This friction is purposeful and helps us gain conviction in what passes our gates.
We combine a mix of traditional heuristics from software development with advanced and novel techniques in AI-testing to deliver truly strong agentic performance in production. Of course, the entire development to testing to production pipeline is automated - our developers and coding agents get feedback and correct in real-time.
During development
Maintaining high code quality before code reaches professionals.
Testing the software
Every code change must clear 2,000+ mandatory tests before it can merge:
- Playwright automated flow testing
- Regression tests for every single bug and incident we've ever seen
- Functional tests for every feature
- SAST / DAST automated security scanning
- Cursor Bugbot review - an AI reviewer that reads every change and flags likely bugs before a person does
- Claude Code reviews - a second AI reviewer that checks the change against our standards and explains what it found
- Daily Cursor code scanning and security reviews
Testing the Rightview agent
Ensuring improvements to the agent are truly progressive:
- Golden-set evaluation on every single production release - we grade each release against a curated set of questions with known-correct answers, so we can prove it still gets them right
- Statistical analysis at scale - we run the new version and the current one against a large volume of real-world cases and compare the results, so an improvement in one area never quietly makes something else worse
In production
Identifying issues in real time and guarding against failures.
- Comprehensive logging, tagged by service line
- Live answer-evaluation metrics - hallucination detection, agentic planning, and tool-call quality, measured on real traffic
- Observability across the stack
Compliance and documentation
Rightview has partnered with Vanta for SOC 2 compliance. We've already achieved HIPAA compliance. View our trust center here: trust.rightview.ai.